



Premium File
50 Q&A
$76.99$69.99
VMware 5V0-34.19 Exam Questions & Answers, Accurate & Verified By IT Experts
Instant Download, Free Fast Updates, 99.6% Pass Rate
50 Questions & Answers
Last Update: Sep 21, 2026
$69.99
VMware 5V0-34.19 Exam Screenshots
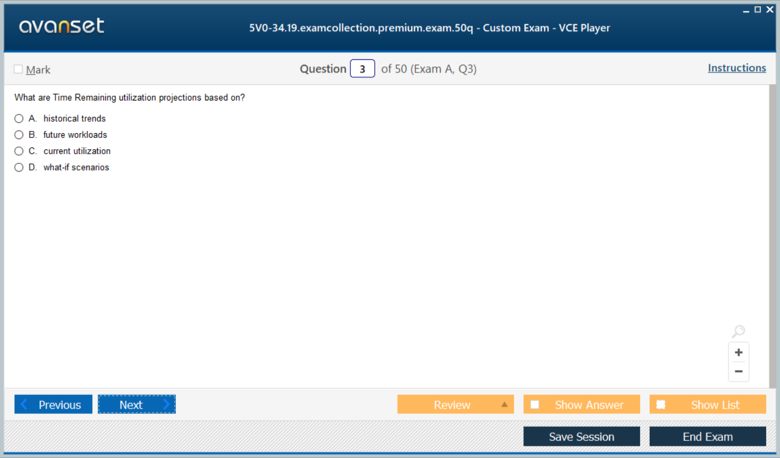
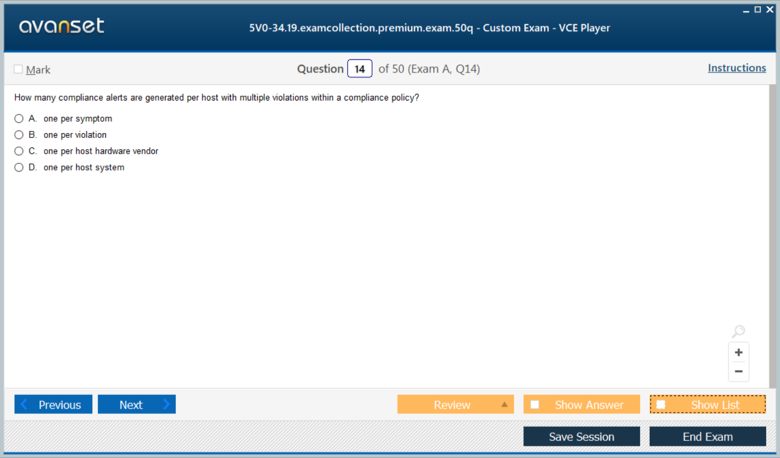
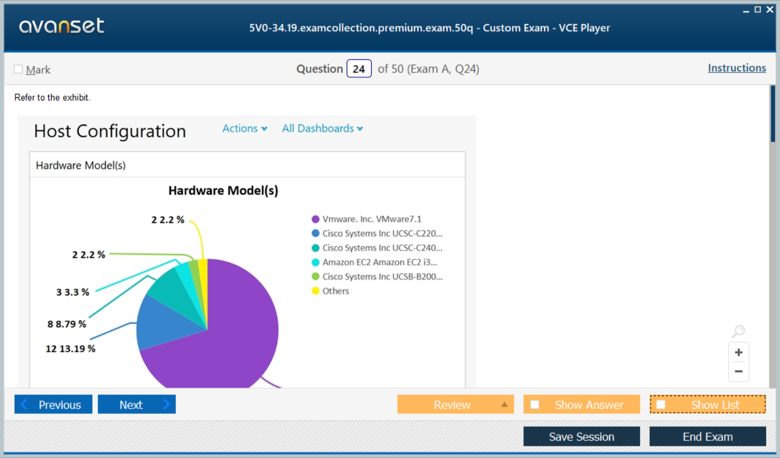
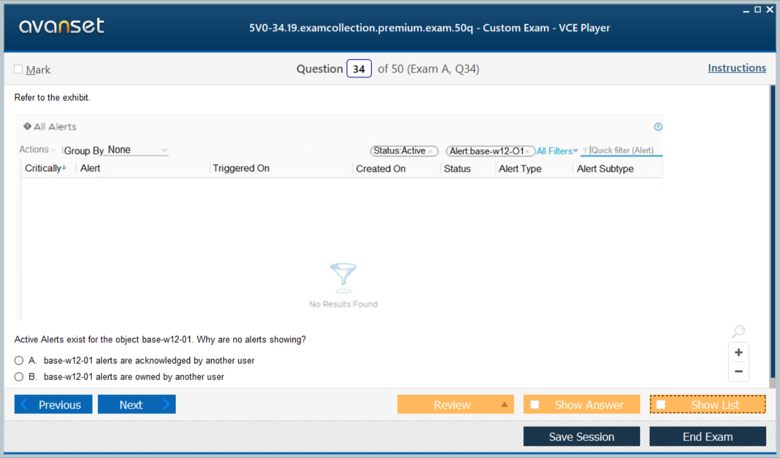
VMware 5V0-34.19 Practice Test Questions in VCE Format
| File | Votes | Size | Date |
|---|---|---|---|
File VMware.actualtests.5V0-34.19.v2026-09-13.by.emily.22q.vce |
Votes 2 |
Size 705.45 KB |
Date Sep 13, 2026 |
VMware 5V0-34.19 Practice Test Questions, Exam Dumps
VMware 5V0-34.19 (VMware vRealize Operations 7.5) exam dumps vce, practice test questions, study guide & video training course to study and pass quickly and easily. VMware 5V0-34.19 VMware vRealize Operations 7.5 exam dumps & practice test questions and answers. You need avanset vce exam simulator in order to study the VMware 5V0-34.19 certification exam dumps & VMware 5V0-34.19 practice test questions in vce format.
The VMware vRealize Operations 7.5 (5V0-34-19) exam belongs to an older operations-management generation. Historical exam material identifies capacity planning, health, performance optimization, remote checks, alerts, dashboards, policies, monitoring, and cluster availability as important areas. The code is absent from Broadcom’s current 2026 VMware certification catalog and should be treated as legacy study material rather than a current certification target.
The product itself also predates later vRealize Operations 8.x, Aria Operations, and today’s VCF Operations naming. That makes version discipline essential. The older interface and algorithms should not be assumed to match modern VCF 9 behavior. What remains valuable is the operations method: collect telemetry, model capacity, detect abnormal conditions, prioritize actionable alerts, and correlate evidence before changing infrastructure.
An environment can look healthy today while being unable to survive growth or maintenance next month. vRealize Operations used demand, allocation, trend, and time-remaining concepts to help administrators reason about headroom. The useful question is not “how much CPU is used?” but “how long until the service objective can no longer be met under expected growth and failure conditions?”
Capacity models need context. Allocated vCPU can greatly exceed physical CPU without producing immediate contention, while memory pressure or storage latency may become critical earlier. A conservative service may plan around reserved capacity, whereas a highly consolidated environment may use measured demand. The model should reflect the risk tolerance and workload behavior of the organization.
Automated or recommended workload movement can improve balance, but relocation is not a substitute for root-cause analysis. CPU ready time, memory contention, datastore latency, network saturation, and noisy neighbors can create similar user complaints. Before moving a virtual machine, determine whether the destination has the right resources and whether the source problem is actually local.
Use correlated metrics over time. A short CPU spike during a batch job is different from sustained contention during business hours. If multiple workloads on one datastore degrade together, storage becomes more likely than individual guest configuration. Optimization should reduce recurring risk, not simply make a dashboard turn green for a few minutes.
vRealize Operations could combine symptoms into alert definitions and then use policies to determine thresholds and relevance. This is powerful but can create alert fatigue when every technical anomaly becomes a page to an operator. A useful alert should represent a condition that requires action or investigation, carry enough context to prioritize it, and reach the team capable of fixing it.
Tune alerts with operational feedback. If a threshold fires every morning during a known batch window and no service is affected, either the threshold or the policy context is wrong. If a critical failure occurs with no alert, the symptom model may be incomplete. Monitoring quality is measured by decision support, not by alert volume.
A dashboard is useful when it helps answer a question such as which clusters are approaching capacity, which virtual machines are experiencing contention, or which datastores have abnormal latency. Filling a screen with unrelated metrics creates visual noise. Views and reports should be designed for an audience and a recurring decision.
Role-specific dashboards are often more effective than one universal page. A capacity planner needs growth and reclaim information; a service owner needs health and business-impact indicators; an infrastructure engineer may need host and datastore detail. The same telemetry can be presented differently without changing the underlying data.
Historical 7.5 material includes application-oriented remote checks such as ICMP, HTTP, and UDP. These checks help answer whether a service endpoint is reachable rather than only whether its virtual machine is powered on. That distinction is essential because infrastructure health and application availability are not the same thing.
Design checks from the user path. A web server with healthy CPU and memory can still be unavailable because of DNS, network, certificate, or application failure. A remote check provides evidence at a higher layer, but it also has dependencies of its own. The monitoring source must have network reachability and should be positioned where its result represents the intended consumer.
Operations platforms are most valuable during incidents, so their own availability matters. vRealize Operations used master, data, remote collector, and high-availability roles to support resilience and scale. A replica node could protect against a single-node failure in an HA design, but the overall deployment still depended on storage, networking, DNS, time, and sufficient cluster resources.
Do not create a monitoring architecture that fails with the environment it is meant to observe. If all collectors, analytics nodes, and dependencies share one failure domain, a site event can remove both the service and the evidence. Remote collection and distributed design should reflect the infrastructure’s fault domains and support model.
Policies can alter thresholds, capacity assumptions, alert behavior, and other settings for different object groups. That makes it possible to monitor production databases differently from development web servers. The danger is policy sprawl: when many overlapping policies exist, administrators may not know which setting actually applies.
Keep policy inheritance understandable. Document why an override exists and which group receives it. When an alert behaves unexpectedly, inspect effective policy before changing the global threshold. Good monitoring architecture is governed configuration, not a collection of one-off exceptions.
A later professional path appears in VMware Cloud Operations, while current VCF 9 integrates operations more tightly into the private-cloud platform. Product names, data models, and workflows changed, so 5V0-34-19 should not be used as a current feature reference.
The older exam still teaches a durable workflow: establish a baseline, detect deviation, correlate symptoms, understand capacity and policy context, and verify the result of remediation. That same discipline supports modern VCF Support work, where troubleshooting depends on evidence from multiple services rather than one console.
Create a virtual machine that appears slow and then reproduce the symptom through different causes: CPU contention, memory pressure, storage latency, network reachability, or an application endpoint failure. Use metrics, alerts, dashboards, and remote checks to distinguish them. This is more valuable than memorizing which screen contains a particular chart.
Also practice capacity scenarios. Add projected workloads, change growth assumptions, reclaim oversized resources, and compare the effect of allocation-based versus demand-based thinking. The strongest preparation for operations work is learning to explain why the platform produced a recommendation and when that recommendation should or should not be followed.
In 2026, the right way to read 5V0-34-19 is historically. It shows how VMware operations certification emphasized capacity, health, policies, and troubleshooting before the Aria and VCF eras. Use the legacy blueprint to strengthen analytical habits, then validate modern product behavior and certification requirements against current Broadcom documentation.
Reclaim recommendations require judgment. An oversized virtual machine can appear to waste resources, but reducing it blindly may remove burst capacity that protects a latency-sensitive service. Compare recommendation history with workload schedules, maintenance windows, business peaks, and application owner expectations. Rightsizing should be a controlled change with post-change validation, not an automatic response to every efficiency suggestion.
What-if analysis is useful because capacity decisions are rarely limited to organic growth. Teams may need to add a new application, remove a host for maintenance, consolidate clusters, or plan a hardware refresh. Model the proposed change before committing resources, then compare the forecast with observed behavior after implementation. The gap between model and reality is valuable feedback for improving future assumptions.
Monitoring design should include data quality. Stale adapters, collection gaps, clock skew, missing credentials, or disconnected endpoints can produce dashboards that look complete while silently omitting part of the environment. Add checks for collector health and data freshness. Before trusting a capacity or performance conclusion, confirm that the expected objects are actually being collected and that their timestamps are current.
Incident review closes the operations loop. After resolving a problem, record which alert fired, which signal identified the root cause, which noise delayed diagnosis, and whether the threshold or dashboard should change. Operations tooling improves when real incidents refine policies. Without that feedback, teams accumulate alerts and reports that reflect old assumptions rather than the failures they actually experience.
Object relationships are critical when interpreting vRealize Operations evidence. A virtual-machine alert can originate from a datastore, host, cluster, adapter, or application dependency, so the visible object is not always the fault domain. Follow parent-child and dependency relationships before changing thresholds or allocating resources. If several virtual machines show the same latency increase at the same time, a shared datastore or host is a stronger hypothesis than ten unrelated guest problems.
Custom dashboards and super metrics should answer operational questions rather than display every available measurement. Combine signals only when the result has a clear interpretation, such as showing demand against usable capacity or correlating latency with contention during a known business window. Document what each derived metric means and which source objects feed it. Otherwise, a sophisticated dashboard can become harder to trust than the raw evidence it was meant to simplify.
Adapter maintenance belongs in capacity accuracy as well. When an adapter stops collecting or permissions change, historical data can remain visible and create the impression that the environment is healthy even though new evidence is missing. Operations teams should monitor adapter status, collection intervals, and object freshness as part of platform health. Forecasting from stale data is not merely a monitoring problem; it can produce incorrect procurement, rightsizing, and consolidation decisions.
Go to testing centre with ease on our mind when you use VMware 5V0-34.19 vce exam dumps, practice test questions and answers. VMware 5V0-34.19 VMware vRealize Operations 7.5 certification practice test questions and answers, study guide, exam dumps and video training course in vce format to help you study with ease. Prepare with confidence and study using VMware 5V0-34.19 exam dumps & practice test questions and answers vce from ExamCollection.
Purchase Individually
Top VMware Certifications




Top VMware Certification Exams
Site Search:

SPECIAL OFFER: GET 10% OFF

Pass your Exam with ExamCollection's PREMIUM files!
SPECIAL OFFER: GET 10% OFF
Use Discount Code:
MIN10OFF
A confirmation link was sent to your e-mail.
Please check your mailbox for a message from support@examcollection.com and follow the directions.

Download Free Demo of VCE Exam Simulator
Experience Avanset VCE Exam Simulator for yourself.
Simply submit your e-mail address below to get started with our interactive software demo of your free trial.