



Premium File
110 Q&A
$76.99$69.99
EMC E20-368 Exam Questions & Answers, Accurate & Verified By IT Experts
Instant Download, Free Fast Updates, 99.6% Pass Rate
110 Questions & Answers
Last Update: Sep 15, 2026
$69.99
EMC E20-368 Exam Screenshots
EMC E20-368 Practice Test Questions in VCE Format
| File | Votes | Size | Date |
|---|---|---|---|
File EMC.Test4prep.E20-368.v2026-07-06.by.Marcus.67q.vce |
Votes 3 |
Size 60.38 KB |
Date Jul 07, 2026 |
EMC E20-368 Practice Test Questions, Exam Dumps
EMC E20-368 (XtremIO Solutions Specialist Exam for Implementation Engineers) exam dumps vce, practice test questions, study guide & video training course to study and pass quickly and easily. EMC E20-368 XtremIO Solutions Specialist Exam for Implementation Engineers exam dumps & practice test questions and answers. You need avanset vce exam simulator in order to study the EMC E20-368 certification exam dumps & EMC E20-368 practice test questions in vce format.
E20-368 was Dell EMC’s Specialist - Implementation Engineer, XtremIO Solutions exam. Its later blueprint covered both XtremIO X1 and X2 environments and listed 105 minutes for roughly 60 questions with a 63% passing score. Dell retired the certification exam on February 2, 2024 and migrated the role to the Dell XtremIO Deploy achievement, D-XTR-DY-A-24.
The code is therefore best understood as a legacy implementation benchmark. It remains useful for studying how an all-flash array moves from equipment in a rack to a correctly integrated storage service. Historical candidates were expected to understand hardware, installation, initial configuration, host connectivity, data services, performance, and solution integration. The EMC certifications supply the wider historical context, while current credential planning should use Dell’s active program.
XtremIO X1 and X2 used different hardware generations, so the blueprint expected candidates to recognize components, cluster offerings, and field-replaceable units. That knowledge matters because later configuration assumes the hardware has been cabled and discovered correctly. A management screen cannot compensate for a missing data path, incorrect interconnect, unsupported component, or incomplete installation sequence.
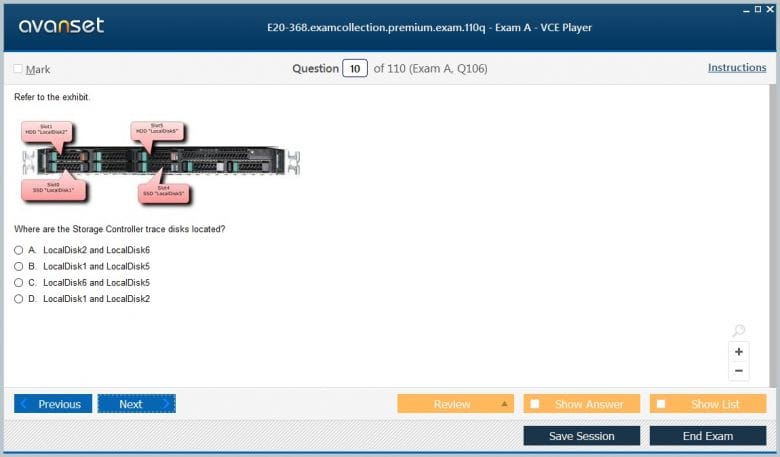
Implementation engineers should be able to read installation documentation and translate it into a physical validation plan. Confirm rack placement, power feeds, cabling, management networks, Fibre Channel or other host connectivity, and support access before initializing the cluster. Document serials, port assignments, switch connections, and management addresses so that troubleshooting does not depend on memory once the environment becomes operational.
The exam description specifically called out installation documentation, cluster cabling, single- versus multi-cluster requirements, logical installation order, and post-installation processes. These are procedural skills, but the reasoning behind them is architectural. Each cable or interface supports a role, and each stage should be verified before moving to the next.
A reliable implementation uses checkpoints. After physical installation, confirm link state. After software initialization, confirm cluster formation. After management configuration, verify access from the intended networks. After storage services are available, perform health checks before presenting production volumes. If a later step fails, those checkpoints provide a known-good boundary that makes diagnosis faster.
The XtremIO Management Server, or XMS, provides management for the storage system and was an important part of the implementation blueprint. Candidates needed to understand deployment options, required software components, connectivity services, and how a cluster is initialized and registered. Management design also influences operational resilience: administrators need reliable access without creating unnecessary exposure.
Initial configuration should include accounts, access methods, time and naming consistency, support connectivity, alerting, and documentation of the management path. The implementation engineer should verify both GUI and command-line access where relevant rather than assuming that one working interface proves the entire management plane is healthy. This becomes particularly important when later automation or support workflows depend on APIs or remote connectivity.
Multi-cluster management adds another operational concern. Administrators need to know which cluster an object belongs to, how management sessions reach it, and how state is represented when several clusters are visible through a common XMS context. A naming convention that works for one array can become ambiguous across a fleet, so implementation documentation should include cluster identity, rack location, host groups, replication relationships, and ownership. Those details reduce the chance that a change is applied to the wrong target during later operations.
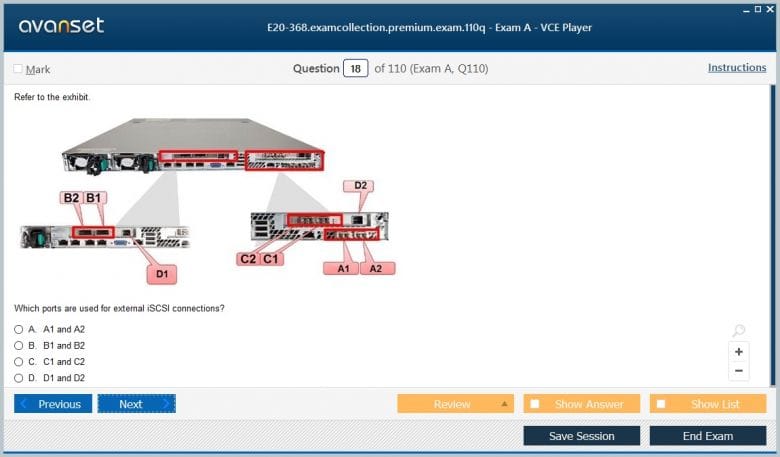
An all-flash array can deliver excellent latency only if the host path is configured correctly. E20-368 expected knowledge of host access and operating-system-specific considerations for VMware, Windows, Linux, and other supported platforms. Fibre Channel zoning, initiator discovery, LUN mapping, multipathing, queue behavior, and host-side settings all affect the result.
Implementation engineers should validate path redundancy and host behavior under controlled failure, not only initial discovery. A volume visible over one path is not a production-ready design. Test the supported multipathing policy, confirm that all intended paths are active or available as designed, and verify that a path loss does not produce unexpected application disruption. These tests connect array configuration to the service the host actually receives.
After installation, the platform must be able to create and manage volumes predictably. Naming, capacity, host mappings, consistency, and lifecycle procedures matter because storage objects quickly multiply in production. The array’s data services also include snapshot capabilities, and the implementation engineer needs to understand how snapshot relationships behave, what limits apply, and how copies interact with application workflows.
Snapshots are useful for rapid point-in-time copies, test environments, and operational recovery, but they should not be confused automatically with an independent backup. A snapshot that depends on the same storage system shares failure domains with that system. The implementation engineer should describe what protection a feature provides and what it does not provide, which prevents the common error of treating every copy mechanism as equivalent.
Data-reduction behavior is also central to the XtremIO design philosophy. Inline deduplication and compression change the relationship between logical capacity and physical media consumption, so capacity discussions should distinguish what hosts allocate from what the array actually stores. An implementation engineer does not need to predict every workload’s reduction ratio perfectly, but should understand that highly duplicate virtual-desktop data behaves differently from already compressed or encrypted content. Baselines and actual reduction statistics are therefore more reliable than optimistic assumptions made during installation.
XtremIO was designed for high-performance workloads, but an implementation can still underperform because of host configuration, fabric constraints, queueing, workload concentration, or incorrect expectations. The blueprint included performance considerations and reporting. That means candidates needed to understand what latency, IOPS, bandwidth, and utilization reveal when considered together.
A good baseline captures normal workload behavior before a problem exists. During validation, compare array metrics with host and application observations. If latency rises while array utilization remains low, the bottleneck may be outside the array. If a small set of hosts creates a disproportionate load, the design may need balancing. Performance troubleshooting is strongest when it follows the I/O path instead of assuming the storage array is always the cause.
Workload testing should also distinguish latency-sensitive random I/O from throughput-oriented sequential activity. Average latency alone can hide short spikes that affect databases or virtual machines, while a throughput number can look impressive even if queueing makes application response inconsistent. Capture a representative workload window, note host queue depth and path distribution, and compare the same measurements after configuration changes. That turns performance validation into an evidence-based acceptance test rather than a one-time benchmark screenshot.
Data-reduction behavior is another reason to validate with realistic workloads. Logical capacity can grow differently from physical consumption when deduplication and compression are effective, so a design should not assume one universal reduction ratio. Measure representative data, preserve enough headroom for growth and maintenance, and distinguish between logical savings and the physical resources that still determine latency, endurance, and failure recovery.
The later E20-368 blueprint included solution-integration topics involving technologies such as RecoverPoint and VPLEX. These combinations can provide replication, mobility, or additional availability options, but they also make change control more demanding. A volume participating in another protection or virtualization layer may have prerequisites that ordinary local volumes do not.
Implementation engineers should map dependencies before making changes. Identify which system owns presentation, which system owns replication, where consistency is controlled, and what sequence is required for maintenance. The related RecoverPoint implementation exam covered the replication side in greater depth, while the XtremIO exam expected enough integration knowledge to deploy the array without breaking those relationships.
When a host cannot access storage, the failure may be in the host, fabric, array mapping, cluster state, or management configuration. When performance changes, the cause may be application demand, pathing, fabric congestion, or storage resources. A good implementation engineer does not start by changing several things at once. The first task is to locate the fault domain.
Use health checks, event data, path state, host logs, fabric information, and performance statistics to narrow the problem. Make one justified change, then verify the effect. This method is especially important in high-performance environments because an apparently small configuration change can affect many workloads simultaneously. Troubleshooting should preserve evidence before remediation where possible.
E20-368 was one of several role-specific XtremIO exams. The E20-526 Technology Architect exam concentrated on positioning and designing solutions, while E20-568 focused on systems administration. An editorial overview of the XtremIO systems-administrator exam provide additional historical context for that operational side of the product family.
Dell’s 2024 transition moved the implementation role to an achievement-based credential, but the practical boundary remains useful. Architects define what the solution should accomplish, implementation engineers build and integrate it, and administrators operate it day to day. Revisiting E20-368 is most valuable when study follows that implementation responsibility: understand the hardware, respect the installation sequence, validate host and service integration, establish a performance baseline, and hand over a system that operations teams can support confidently.
A clean handoff closes the implementation loop. Record cluster identity, software and XMS versions, host mappings, path validation, protection relationships, support contacts, and the performance measurements captured during acceptance testing. Day-two administrators then have evidence of the intended state rather than having to reconstruct design assumptions from an already busy production array.
Implementation is complete only after the consuming host has been validated, not merely after the array reports healthy objects. Confirm the expected paths, run an agreed workload or access test, and record the result. That closes the gap between successful storage configuration and successful application service.
Go to testing centre with ease on our mind when you use EMC E20-368 vce exam dumps, practice test questions and answers. EMC E20-368 XtremIO Solutions Specialist Exam for Implementation Engineers certification practice test questions and answers, study guide, exam dumps and video training course in vce format to help you study with ease. Prepare with confidence and study using EMC E20-368 exam dumps & practice test questions and answers vce from ExamCollection.
Purchase Individually
Site Search:

SPECIAL OFFER: GET 10% OFF

Pass your Exam with ExamCollection's PREMIUM files!
SPECIAL OFFER: GET 10% OFF
Use Discount Code:
MIN10OFF
A confirmation link was sent to your e-mail.
Please check your mailbox for a message from support@examcollection.com and follow the directions.

Download Free Demo of VCE Exam Simulator
Experience Avanset VCE Exam Simulator for yourself.
Simply submit your e-mail address below to get started with our interactive software demo of your free trial.