



Premium File
60 Q&A
$76.99$69.99
IBM C2090-930 Exam Questions & Answers, Accurate & Verified By IT Experts
Instant Download, Free Fast Updates, 99.6% Pass Rate
60 Questions & Answers
Last Update: Oct 21, 2026
$69.99
IBM C2090-930 Exam Screenshots
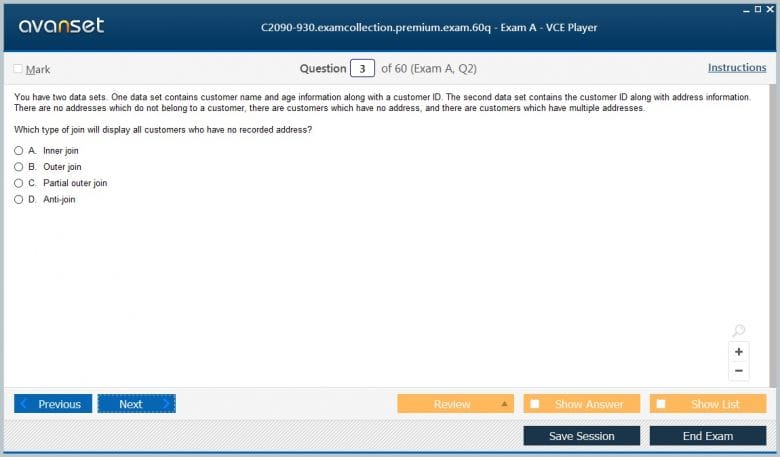
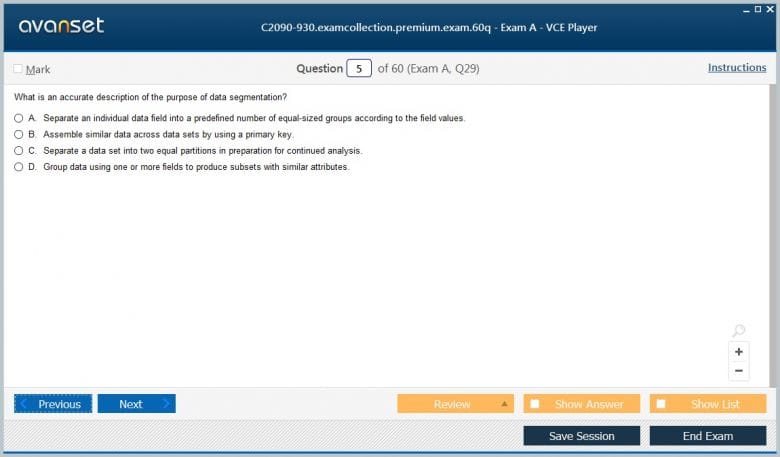
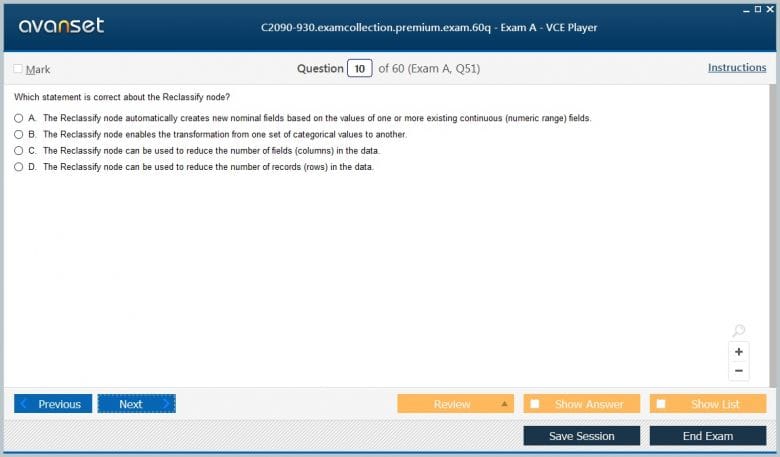
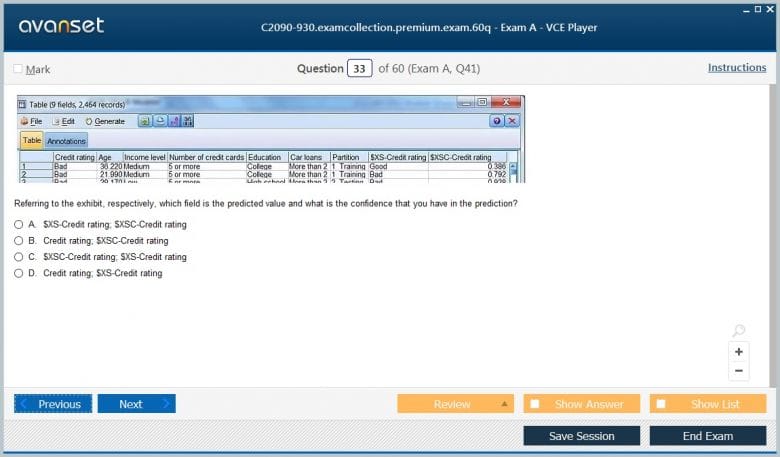
IBM C2090-930 Practice Test Questions in VCE Format
| File | Votes | Size | Date |
|---|---|---|---|
File IBM.pass4sure.C2090-930.v2026-09-18.by.shadow.31q.vce |
Votes 1 |
Size 374.94 KB |
Date Sep 18, 2026 |
File IBM.realtests.C2090-930.v2020-07-24.by.alfie.30q.vce |
Votes 2 |
Size 36.92 KB |
Date Jul 24, 2020 |
IBM C2090-930 Practice Test Questions, Exam Dumps
IBM C2090-930 (IBM SPSS Modeler Professional v3) exam dumps vce, practice test questions, study guide & video training course to study and pass quickly and easily. IBM C2090-930 IBM SPSS Modeler Professional v3 exam dumps & practice test questions and answers. You need avanset vce exam simulator in order to study the IBM C2090-930 certification exam dumps & IBM C2090-930 practice test questions in vce format.
C2090-930, IBM SPSS Modeler Professional v3, is explicitly listed by IBM as withdrawn. IBM’s archived certification page describes a 60-question exam built around business understanding, data preparation, data understanding, modeling, evaluation, deployment, and SPSS Modeler functionality. The structure matters because it reflects a complete analytics workflow rather than a collection of algorithms.
The most durable lesson is methodological. IBM’s blueprint starts with CRISP-DM and business objectives, then moves through preparing and understanding data before modeling, evaluating, and deploying. That order protects teams from a common failure: building a technically impressive model that does not answer the business question or cannot be operated with reliable data. Modeler’s visual streams make the workflow visible, but the reasoning behind the nodes is the real skill.
Business understanding comes before algorithm selection. Define the decision the model is supposed to improve, the target outcome, the constraints, the cost of errors, and what success will look like after deployment. A churn model, fraud model, demand forecast, or propensity model can use similar techniques but require different evaluation because the business consequences differ. Translating an objective into a measurable data-mining goal is therefore a core analytical task.
CRISP-DM is iterative rather than strictly linear. Data understanding can expose a flaw in the original question; modeling can reveal that important predictors are missing; deployment can uncover latency or governance constraints that change the feasible solution. Good candidates expect to revisit earlier stages. The broader distinction between data science and data analytics is useful context because successful modeling combines statistical technique with problem framing and operational use.
Before transforming data, inspect it. Summary statistics, distributions, visualizations, and audit outputs can reveal missing values, extreme outliers, unexpected categories, impossible ranges, or data that represents a different population than the project assumes. A model can fit flawed data very accurately, so quality review is not a cosmetic cleanup step.
Look for leakage as well. A field may predict the target only because it is created after the outcome occurs. Duplicate records may let the same entity appear in training and test partitions. A timestamp or internal status code may quietly encode information unavailable at prediction time. The exam’s emphasis on data understanding is therefore practical: candidates should be able to recognize when apparent predictive power comes from the data pipeline rather than a transferable relationship.
IBM’s exam objectives referenced transformation and preparation tools such as Derive, Auto Data Prep, Data Audit, Filler, Merge, Append, Sample, Balance, Partition, Select, Filter, and Aggregate. Each node should answer a question. Are values being derived because the raw variable is not useful? Are records being filtered because they are outside the target population? Is balancing needed because a rare class would otherwise be ignored? Is a partition separating model development from evaluation?
A visual stream can become just as opaque as code if nodes are added without explanation. Name branches clearly, document why transformations exist, and preserve raw fields when auditability requires them. When integrating sources, test key uniqueness and row counts before and after a merge. The principles in data integration apply directly: combining data is valuable only when relationships and provenance remain trustworthy.
Training a model and testing it on the same observations gives an optimistic result because the model is rewarded for patterns it has already seen. Partitioning creates separation between fitting and evaluation. In some projects, a third validation partition supports model selection while the test set remains untouched until the end. The exact percentages are less important than the principle that evaluation data must represent future use and remain independent of fitting decisions.
Sampling should preserve the question the model needs to answer. Simple random samples may be appropriate for large balanced populations, while stratified or balanced samples may help expose rare outcomes during development. But changing class proportions can change probability interpretation, so the deployment process may need adjustment. Candidates should understand what sampling changes, not just where the node is located in the palette.
The blueprint covered classification, regression, segmentation, association, auto-modeling, and ensembles. These families answer different questions. Classification assigns cases to categories; regression predicts continuous outcomes; segmentation groups similar observations; association looks for co-occurrence patterns; ensembles combine models to improve stability or accuracy. Picking a technique starts with the target variable and decision context.
Regression is especially useful for understanding the difference between fitting and interpretation. Coefficients, residuals, assumptions, and error metrics tell a richer story than one accuracy number. Regression in machine learning provides helpful conceptual background. The same disciplined questions apply across models: what signal is being learned, what assumptions are being made, and what failure mode matters to the business?
Automated modeling nodes can train and compare multiple algorithms quickly, which is useful when the team needs a strong baseline or wants to explore candidate approaches. Automation does not make the winning model automatically suitable for deployment. A small performance gain may not justify a major increase in complexity, scoring latency, instability, or explanation difficulty.
Evaluate models against business cost as well as statistical metrics. In imbalanced classification, overall accuracy can hide poor detection of the rare class. Precision and recall may trade against each other, and the best threshold depends on false-positive and false-negative costs. An ensemble may improve predictive performance while making governance harder. Model choice is therefore a decision that balances evidence and operational constraints.
IBM’s objectives included Evaluation and Analysis nodes and interpretation of model nuggets. Use them to ask whether performance holds across partitions, segments, time periods, and important business groups. Inspect confusion matrices, lift or gain, error distributions, residual patterns, and other diagnostics appropriate to the model. A model that performs well on average may still fail badly for a critical segment.
Stability matters. If small changes to the training sample produce very different models, deployment risk increases. If the data-generating process changes, a model can degrade even though the original evaluation was sound. Document assumptions and define how performance will be checked after release. That turns evaluation from an exam phase into an operating control.
The archived IBM objectives included exporting data, scoring new observations, and reporting results. Deployment means reproducing the preparation and scoring sequence consistently on new data. Inputs need compatible fields and types, transformations must be applied in the same way, and outputs need to reach a decision process that can use them. A model file without a reliable scoring pipeline is not a deployed analytical solution.
Versioning and monitoring should cover the whole stream. Record which data definition, transformations, model, threshold, and output logic are active. If a model is retrained, compare it with the current production version before promotion. Monitor both technical execution and outcome quality. A scoring job that completes successfully can still produce poor decisions if the population has shifted.
SuperNodes and scripting can improve reuse and automation, but they should make the stream more understandable rather than merely more compact. Encapsulate stable logic, document parameters, and test changes at boundaries. The visual environment is most powerful when it exposes the reasoning of the pipeline to analysts and reviewers.
A useful Modeler stream should produce the same logical result when given the same versioned inputs and settings. That requires more than saving the canvas. Record source definitions, field roles, type decisions, transformations, sampling seeds where applicable, modeling parameters, and the version of the model promoted to scoring. Without this information, a team can reproduce the diagram but not necessarily the analysis.
Scripting and SuperNodes are valuable when they reduce manual variation. A script can standardize repeated preparation or scoring steps; a SuperNode can encapsulate a stable sub-process. Both can also hide important behavior if they are poorly documented. Treat reusable components as governed code: give them clear inputs and outputs, test boundary cases, version changes, and make dependencies visible. This discipline becomes especially important when several analysts reuse the same stream across projects.
Analytical governance should also record where the training data came from and whether the project is allowed to use it for the intended decision. Sensitive attributes, proxies for protected characteristics, retention limits, and explainability requirements can affect modeling choices before any algorithm is trained. Even when the historical exam concentrated on SPSS workflow skills, modern practice benefits from treating data access, model approval, and production monitoring as part of the same lifecycle.
C2090-930 is a legacy exam, but its sequence remains a strong way to study practical predictive analytics: define the business goal, understand and prepare data, compare models honestly, evaluate risk, then deploy a reproducible process. Use IBM certifications for historical IBM context, and use current SPSS Modeler training for present-day interfaces and capabilities.
Go to testing centre with ease on our mind when you use IBM C2090-930 vce exam dumps, practice test questions and answers. IBM C2090-930 IBM SPSS Modeler Professional v3 certification practice test questions and answers, study guide, exam dumps and video training course in vce format to help you study with ease. Prepare with confidence and study using IBM C2090-930 exam dumps & practice test questions and answers vce from ExamCollection.
Purchase Individually
Site Search:

SPECIAL OFFER: GET 10% OFF

Pass your Exam with ExamCollection's PREMIUM files!
SPECIAL OFFER: GET 10% OFF
Use Discount Code:
MIN10OFF
A confirmation link was sent to your e-mail.
Please check your mailbox for a message from support@examcollection.com and follow the directions.

Download Free Demo of VCE Exam Simulator
Experience Avanset VCE Exam Simulator for yourself.
Simply submit your e-mail address below to get started with our interactive software demo of your free trial.