



Premium File
349 Q&A
$76.99$69.99
Google Professional Data Engineer Exam Questions & Answers, Accurate & Verified By IT Experts
Instant Download, Free Fast Updates, 99.6% Pass Rate
Professional Data Engineer Premium File: 349 Questions & Answers
Last Update: Oct 21, 2026
Professional Data Engineer Training Course: 201 Video Lectures
Professional Data Engineer PDF Study Guide: 543 Pages
$79.99
Google Professional Data Engineer Exam Screenshots
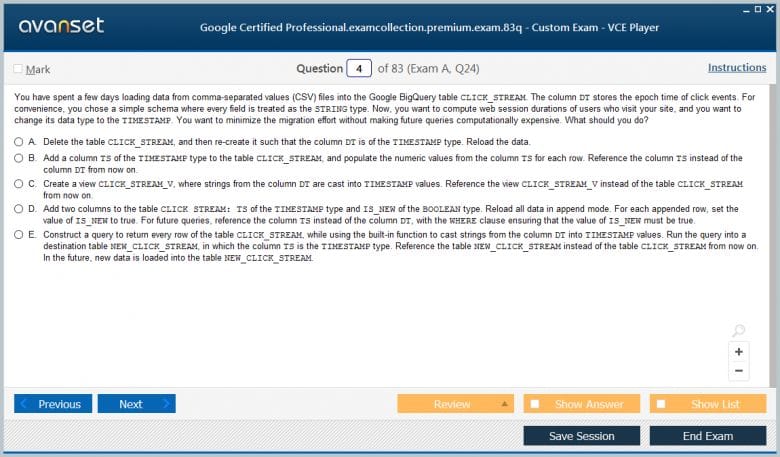
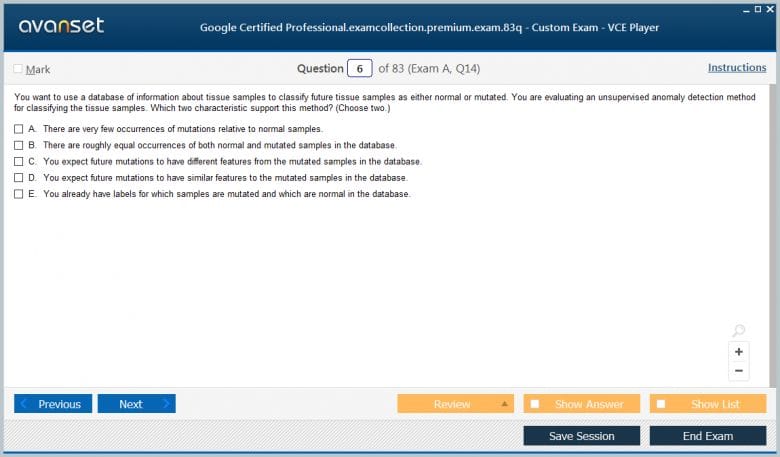
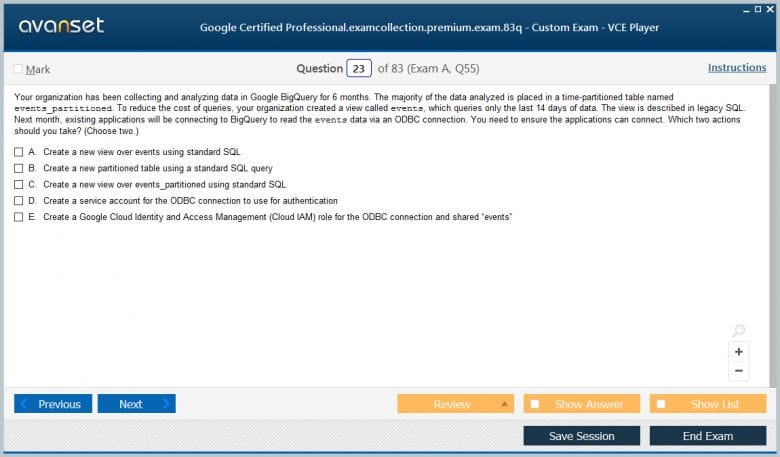
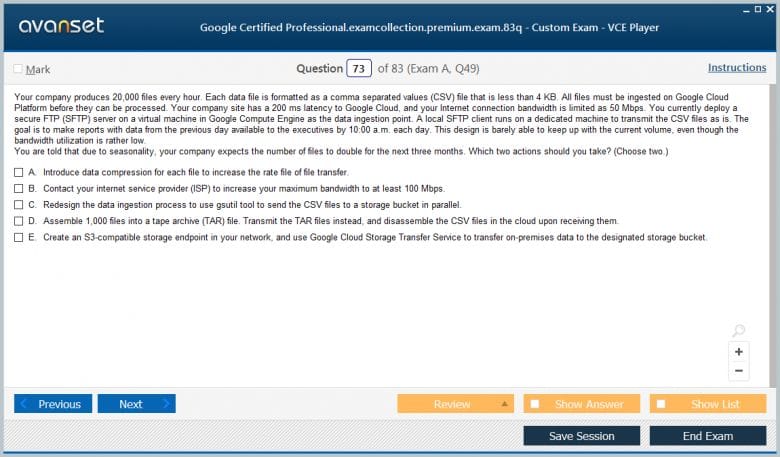
Google Professional Data Engineer Practice Test Questions in VCE Format
| File | Votes | Size | Date |
|---|---|---|---|
File Google.braindumps.Professional Data Engineer.v2026-09-22.by.annabelle.109q.vce |
Votes 1 |
Size 1.37 MB |
Date Sep 22, 2026 |
File Google.examdumps.Professional Data Engineer.v2021-12-27.by.christopher.103q.vce |
Votes 1 |
Size 272.55 KB |
Date Dec 27, 2021 |
File Google.examdumps.Professional Data Engineer.v2021-10-15.by.zhangyan.99q.vce |
Votes 1 |
Size 281.81 KB |
Date Oct 15, 2021 |
File Google.certkey.Professional Data Engineer.v2021-04-19.by.charlotte.93q.vce |
Votes 1 |
Size 406.26 KB |
Date Apr 19, 2021 |
File Google.Prepaway.Professional Data Engineer.v2019-09-09.by.Willie.86q.vce |
Votes 4 |
Size 274.04 KB |
Date Sep 16, 2019 |
File Google.Actualtests.Professional Data Engineer.v2018-11-08.by.Travis.27q.vce |
Votes 14 |
Size 174.69 KB |
Date Nov 16, 2018 |
Google Professional Data Engineer Practice Test Questions, Exam Dumps
Google Professional Data Engineer (Professional Data Engineer on Google Cloud Platform) exam dumps vce, practice test questions, study guide & video training course to study and pass quickly and easily. Google Professional Data Engineer Professional Data Engineer on Google Cloud Platform exam dumps & practice test questions and answers. You need avanset vce exam simulator in order to study the Google Professional Data Engineer certification exam dumps & Google Professional Data Engineer practice test questions in vce format.
Professional Data Engineer is a current Google Cloud professional certification for practitioners who collect, transform, store, govern, and deliver data for analytics and applications. Google’s current standard exam is two hours, uses 40–50 multiple-choice and multiple-select questions, costs $200 before applicable tax, and has no formal prerequisite. Google recommends three or more years of industry experience including at least one year designing and managing solutions with Google Cloud. The current scope emphasizes designing data-processing systems, ingesting and processing data, storing data, preparing data for analysis, and maintaining and automating data workloads. For active credential holders, Google now offers renewal through the standard exam, a shorter one-hour renewal exam, or designated Google Skills courses or skill badges; the standard and renewal exams extend validity for two years, while the Google Skills renewal route currently grants one year.
The exam is easiest to understand as a sequence of data decisions rather than a catalog of products. The Professional Data Engineer certification material should be connected to source characteristics, latency, schema, scale, governance, reliability, consumers, and operating cost. A pipeline is successful only when users can trust the resulting data and the team can explain how it arrived there.
Data systems exist to support decisions, models, applications, and operational processes. A team should identify who consumes the data, how fresh it must be, what correctness means, how long it should be retained, and what happens when the pipeline is late or incomplete. Those requirements determine whether the solution needs streaming, batch processing, a warehouse, an operational database, a lake, or a combination of systems.
Architects should also define ownership. Data that has no accountable producer or steward becomes difficult to trust. Contracts around schema, semantics, quality, and update frequency reduce the chance that one team changes a source field and silently breaks several downstream dashboards. Certification scenarios often reward designs that make data responsibilities explicit instead of relying on informal knowledge.
Batch ingestion is appropriate when sources arrive on a schedule or when latency requirements are relaxed, while streaming systems support near-real-time events and continuous processing. The Pub/Sub model is relevant for decoupling producers and consumers, buffering bursts, and distributing events. Engineers still need to consider duplicates, ordering, acknowledgement behavior, replay, dead-letter handling, and idempotent downstream processing.
Ingestion design should include failure recovery before production traffic arrives. If a consumer is unavailable for several hours, can it replay safely? If a batch file is partially delivered, how is completeness detected? If a source emits malformed data, is it quarantined or allowed to poison the main table? Reliable ingestion preserves enough metadata to answer where a record came from and whether it was transformed successfully.
Change data capture introduces another pattern: continuously propagate database changes without repeatedly scanning whole tables. CDC can support migrations, operational analytics, and synchronization, but engineers must understand ordering, transaction boundaries, schema evolution, replay, and how deletes are represented. A downstream system that ignores tombstones or transaction context can become subtly inconsistent.
Dataflow provides managed execution for Apache Beam pipelines and can handle both batch and streaming processing with one programming model. It is useful when teams want autoscaling and managed orchestration around transformations, windows, triggers, and event-time processing. The Dataflow processing model becomes clearer when candidates reason about bounded versus unbounded data and how late events affect results.
Dataproc provides managed Hadoop and Spark environments for workloads that benefit from those ecosystems or need easier migration from existing big-data tooling. The Dataflow and Dataproc distinction is less about which service is newer and more about workload fit, operational model, frameworks, portability, and how much cluster control the team needs.
BigQuery separates large-scale analytical storage and compute from the operational concerns of traditional database servers, but efficient use still depends on schema and workload design. Partitioning, clustering, appropriate data types, selective queries, materialized or aggregated structures, and workload management can reduce both latency and cost. Analysts should avoid patterns that repeatedly scan unnecessary columns or full historical tables when a narrower design would answer the question.
The BigQuery analytics model should be studied together with governance. Datasets need clear access rules, locations, retention expectations, labels, lineage, and ownership. A warehouse can centralize valuable business information, which makes over-broad access especially risky. Engineers should design secure sharing without creating dozens of uncontrolled copies.
Analytical modeling should serve how users ask questions. Wide denormalized tables can simplify reporting, while normalized or nested structures may reduce duplication or better represent repeated fields. Engineers should choose deliberately and document metric definitions so two teams do not calculate the same business measure differently. Semantic consistency is as important as query speed.
Object storage is useful for raw files, archives, exports, and lake-style datasets, while databases and warehouses serve more structured access patterns. The Google Cloud storage options differ in durability, latency, access interface, lifecycle controls, and cost. Data engineers should not use one storage product simply because it is familiar.
Lifecycle policy can be as important as initial placement. Large data estates accumulate historical objects, intermediate files, duplicate extracts, and temporary outputs unless teams define retention and archival rules. Storage classes, deletion policies, table expiration, and curated zones can reduce cost and compliance risk. The ability to reproduce data from authoritative sources should guide which intermediate artifacts truly need long-term retention.
A pipeline can run successfully while producing wrong answers. Engineers should test schema, nullability, uniqueness, referential expectations, ranges, freshness, volume, and business rules where appropriate. Quality checks should be tied to response actions: block publication, quarantine bad records, alert an owner, or allow degraded output with a clear warning depending on the severity and consumer expectations.
Lineage helps teams understand how a table or field was produced and which downstream assets depend on it. This becomes critical during schema changes and incidents. A change to a source column may affect transformations, dashboards, ML features, exports, and regulatory reports. Engineers should preserve metadata that supports impact analysis rather than treating pipeline code as the only documentation.
Backfills and reprocessing need explicit design. Correcting historical data may require rerunning months of partitions, replaying events, or rebuilding derived tables. Pipelines should separate event time from processing time and avoid logic that produces different answers simply because it ran on a later date. Idempotent outputs and partition-aware processing make recovery far safer.
Data engineers frequently handle sensitive customer, financial, or operational information. Access should use groups and workload identities with least privilege, while encryption, regional placement, masking, tokenization, or policy tags may be required for specific datasets. Service accounts used by pipelines should not automatically inherit broad human-admin roles. Temporary staging areas and exports need the same security attention as final curated tables.
The related Professional Cloud Security Engineer perspective is useful because data systems cross many boundaries. A pipeline may read from one project, process in another, and publish to a third. Governance should follow the data through each step and produce audit evidence that shows who accessed or changed sensitive assets.
Data contracts can make schema evolution safer. Producers can publish expected fields, types, semantics, and compatibility rules, while consumers validate that changes do not silently alter meaning. Adding a nullable field is usually easier to absorb than changing a timestamp to a string or redefining a revenue metric. Versioned contracts help teams coordinate without freezing every source permanently.
Privacy engineering may require minimizing fields before they enter broad analytical systems. Tokenization, pseudonymization, aggregation, or selective projection can reduce exposure while preserving analytical value. The best control is sometimes not giving a pipeline access to sensitive raw attributes at all, rather than relying on every downstream consumer to handle them perfectly.
Build a small project that ingests files and events, validates them, transforms them, stores curated outputs, and serves an analytical query. Add late data, duplicate messages, schema changes, malformed records, a failed worker, and a backfill. Measure cost and latency before and after optimization. Then document lineage and access so another engineer can understand the system without reading every line of code.
The Professional Data Engineer study experience is most valuable when it encourages applied reasoning. The exam tests whether a candidate can choose and operate a data system under real constraints. Strong preparation combines product knowledge with data modeling, failure handling, governance, automation, and the ability to explain why one architecture better fits the business requirement than another.
Operations should include capacity and cost review. Streaming pipelines can accumulate backlog, warehouses can grow expensive through broad scans, and temporary staging data can persist indefinitely. Engineers should monitor throughput, lag, failed records, slot or compute use, storage growth, and per-workload spend so performance or financial problems are detected before consumers notice them.
A final preparation exercise should include a controlled schema change. Add a field, rename or deprecate another field, and observe which transformations, queries, dashboards, and downstream jobs are affected. Then design a compatibility period and backfill strategy. This exposes a central truth of professional data engineering: pipelines are long-lived contracts between teams, and safe evolution matters just as much as initial throughput or query performance.
Recovery drills should include replaying a failed partition or event window without duplicating published results. That forces candidates to think about checkpoints, idempotency, watermarking, output ownership, and how downstream consumers recognize a corrected dataset.
Design recovery before the first failure, not after it.
Go to testing centre with ease on our mind when you use Google Professional Data Engineer vce exam dumps, practice test questions and answers. Google Professional Data Engineer Professional Data Engineer on Google Cloud Platform certification practice test questions and answers, study guide, exam dumps and video training course in vce format to help you study with ease. Prepare with confidence and study using Google Professional Data Engineer exam dumps & practice test questions and answers vce from ExamCollection.
Purchase Individually
Google Professional Data Engineer Video Course
Top Google Certifications




Top Google Certification Exams
Site Search:

SPECIAL OFFER: GET 10% OFF

Pass your Exam with ExamCollection's PREMIUM files!
SPECIAL OFFER: GET 10% OFF
Use Discount Code:
MIN10OFF
A confirmation link was sent to your e-mail.
Please check your mailbox for a message from support@examcollection.com and follow the directions.

Download Free Demo of VCE Exam Simulator
Experience Avanset VCE Exam Simulator for yourself.
Simply submit your e-mail address below to get started with our interactive software demo of your free trial.
simply put, I wouldn’t have made it without these Professional Data Engineer questions and answers… I realized just days before the exam that I needed to do so much in order to pass this test… and these materials helped me just even though i had so little time! Am very grateful to ExamCollection!
@gavin, these google professional data engineer vce files will certainly be of great help in your exam but i wouldn’t advise you to shut out other learning materials… it is wiser to combine varied resources which will make sure you don’t struggle at all during the exam. wish you luck☺
will the braindumps for Professional Data Engineer exam be enough to get ready for this test?? am using them to prepare and so far they seem okay to me but want to hear some advice from those who already passed the exam…
Guys, I have some advice for candidates… using these Professional Data Engineer practice tests can save you a great deal of time and still be very effective . they saved me just when I thought I was out of time… thumbs up ExamCollection for this superb materials and for providing this treasure just for free!
@jace, i used several materials but can surely say that i aced this test thanks to these dumps for Professional Data Engineer exam… they helped me build strength in all the required areas so the exam was easy for me. their level of validity is commendable! you should go for these braindumps if you want to score high, they will help you too!
anyone who has passed this exam recently? did you use these Google Professional Data Engineer exam dumps? if yes to what extend were they helpful?
Hi,
Need help to get practice exam for google data engineer.
Tnx.
Please can you tell me where I can find the download. Many thanks.
Need it urgently.